Comparative model evaluation
Evaluate candidate models with the same immutable dataset and policy.
Activity responsibilities
| Activity | Responsibility |
|---|---|
freeze-evaluation-set | Execute the freeze evaluation set stage and publish its declared outputs for downstream activities. |
evaluate-model-a | Execute the evaluate model A stage and publish its declared outputs for downstream activities. |
evaluate-model-b | Execute the evaluate model B stage and publish its declared outputs for downstream activities. |
evaluate-model-c | Execute the evaluate model C stage and publish its declared outputs for downstream activities. |
compare-metrics | Execute the compare metrics stage and publish its declared outputs for downstream activities. |
approve-candidate | Execute the approve candidate stage and publish its declared outputs for downstream activities. |
Inputs
- Candidate models
- Evaluation set
- Acceptance policy
Outputs
- Metric reports
- Decision record
- Approved candidate
Provenance to preserve
- Model versions
- Evaluation runtime
- Approval rationale
Source bundle
The executable workflow and its implementation files are maintained in the separate AkôFlow examples repository. The documentation intentionally keeps code, container recipes, generators, and validation scripts out of the narrative page.
Open the complete source bundle ↗Verified local execution
These captures and the output manifest were produced by the fixture's local Docker run and validator. They are published with the same bundle as the runnable files.
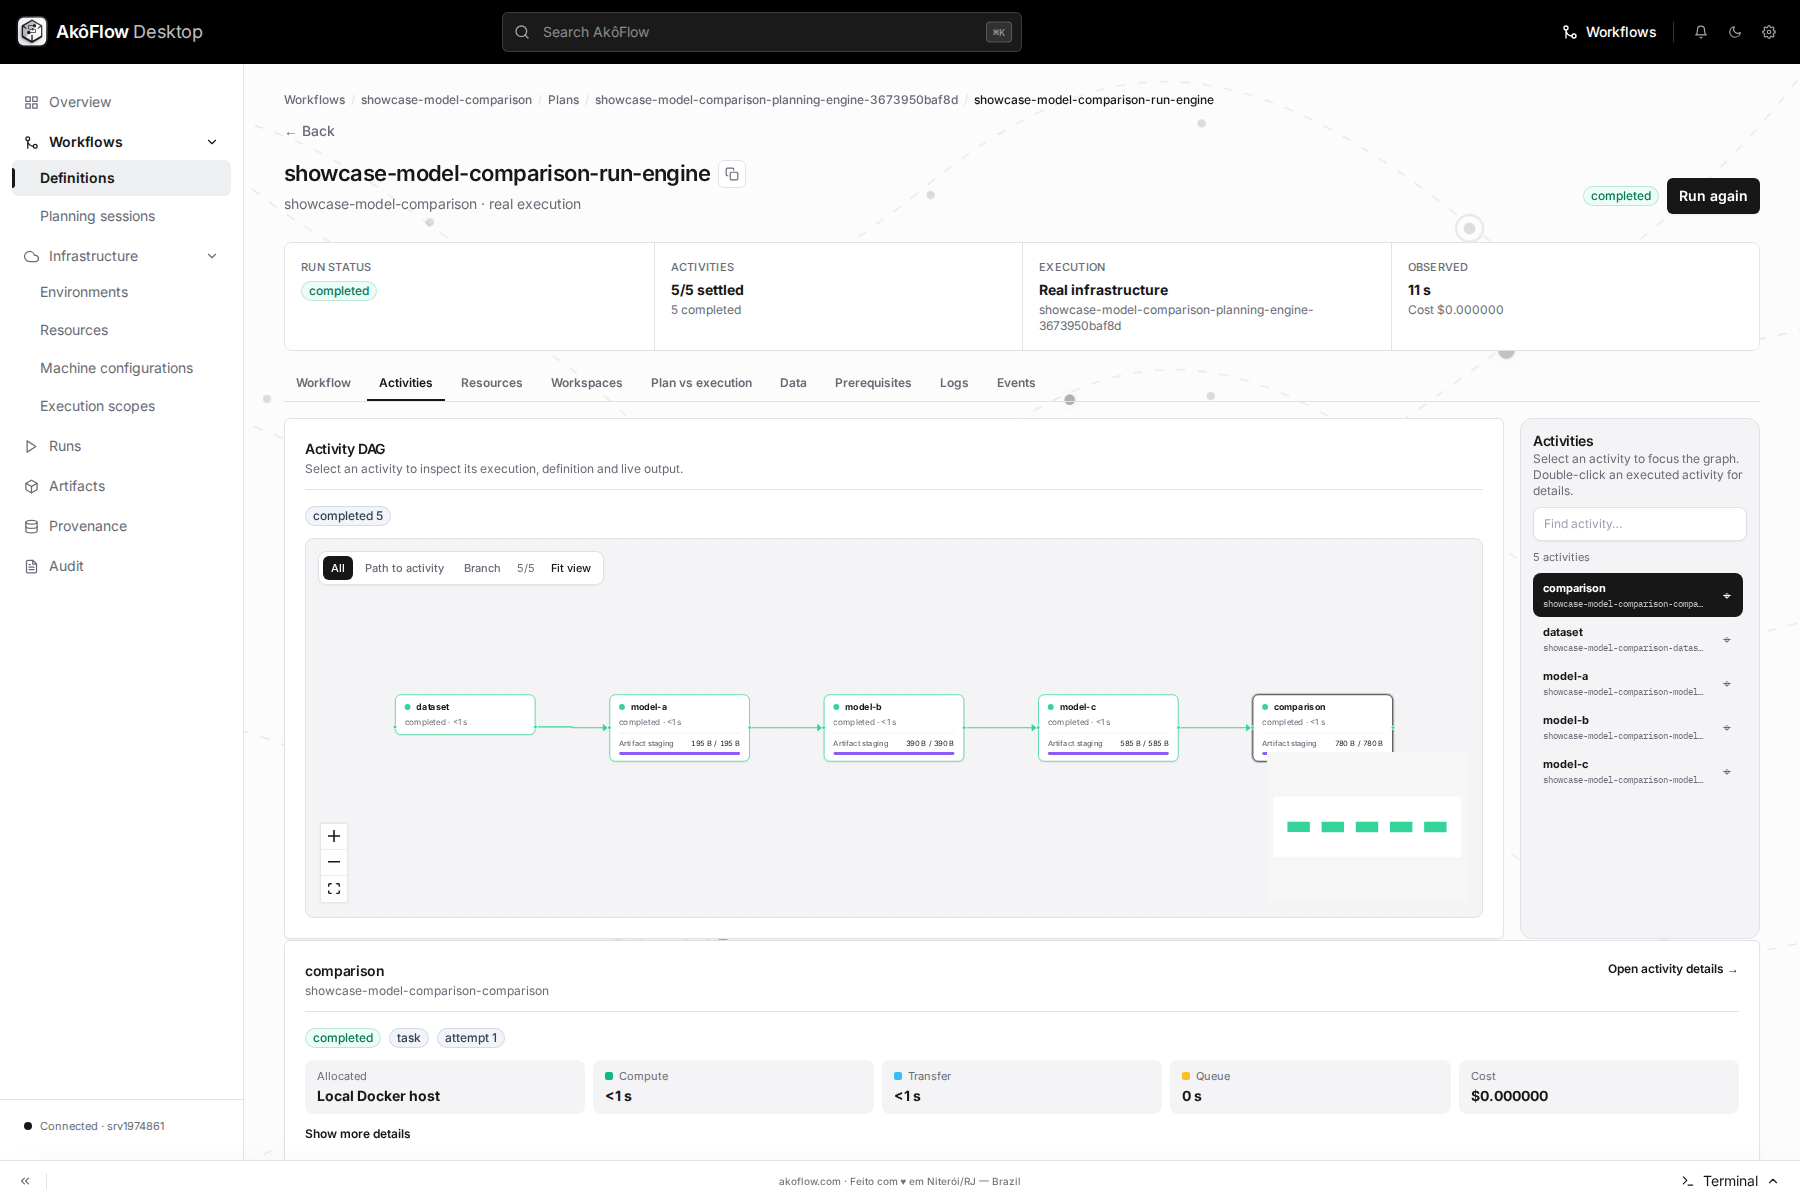
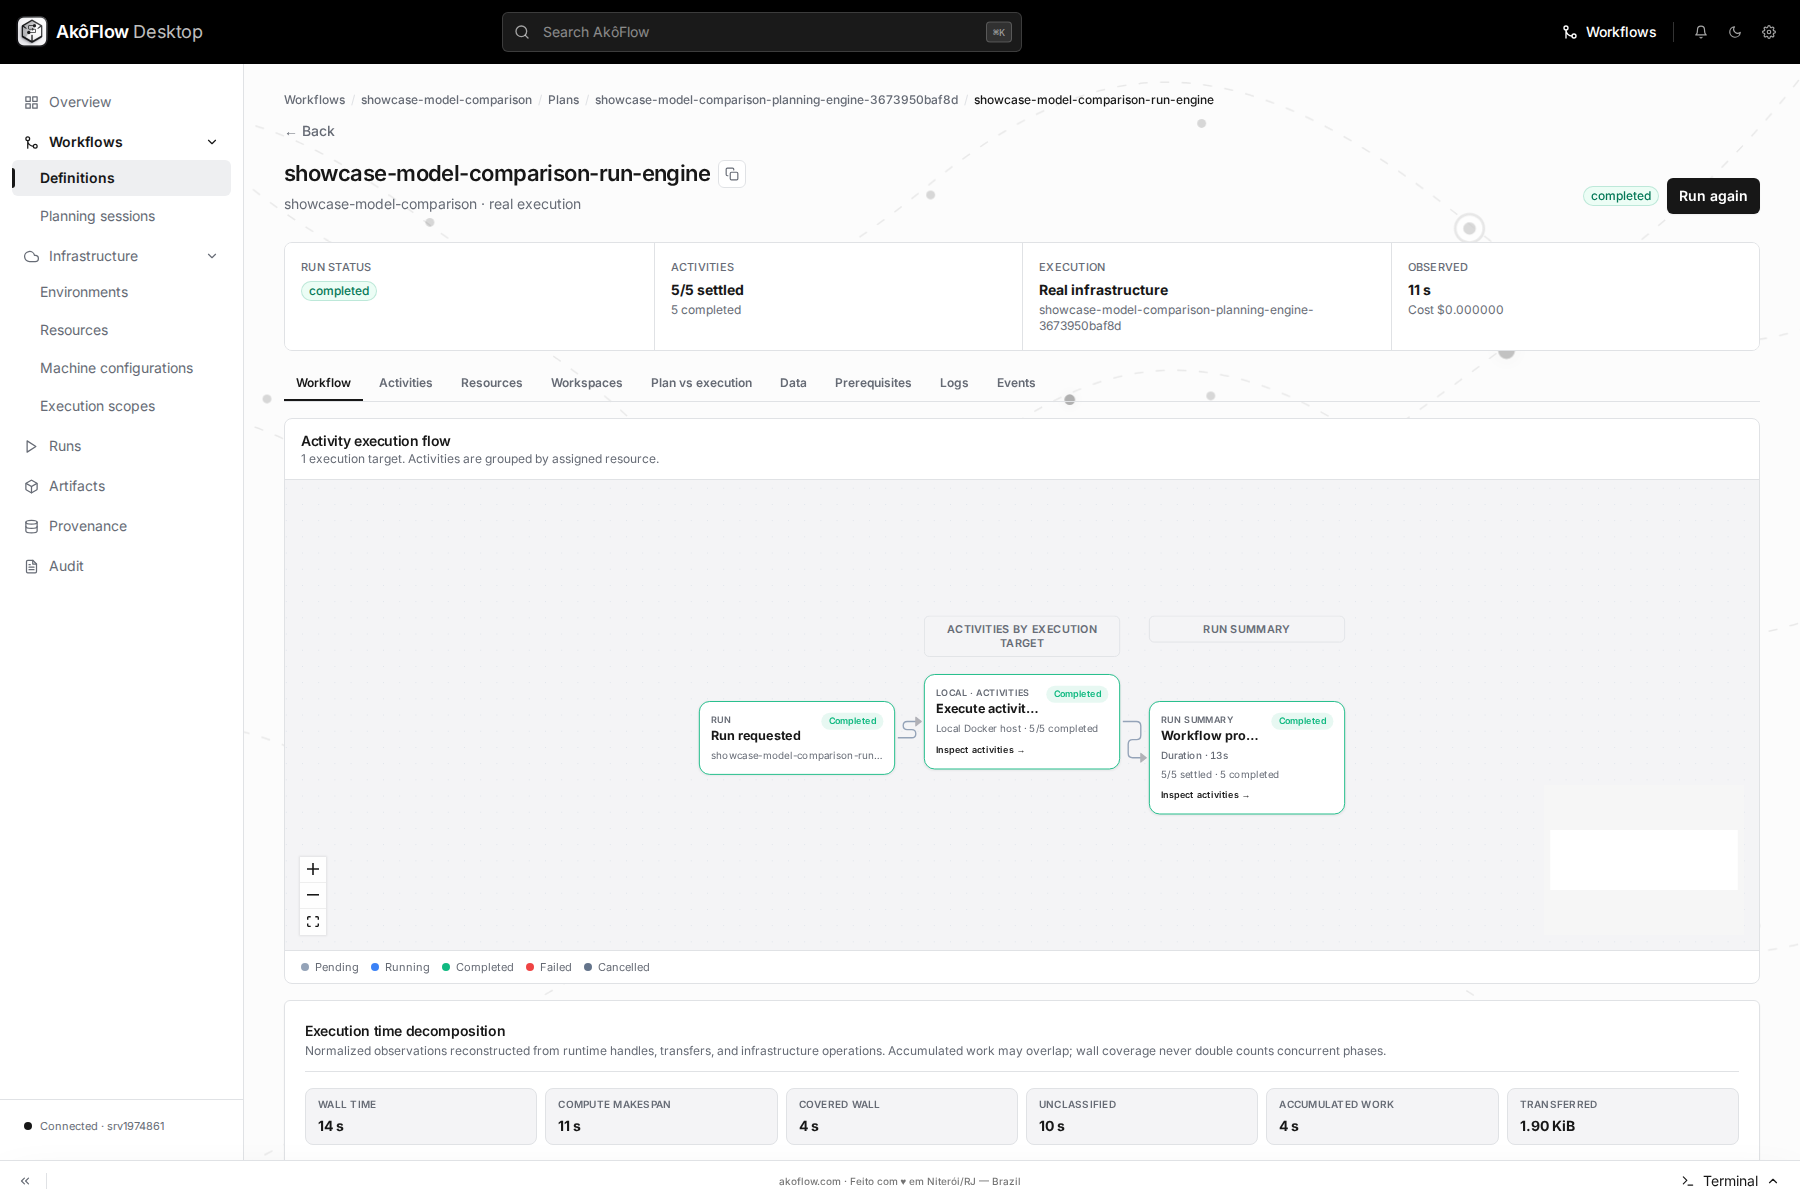
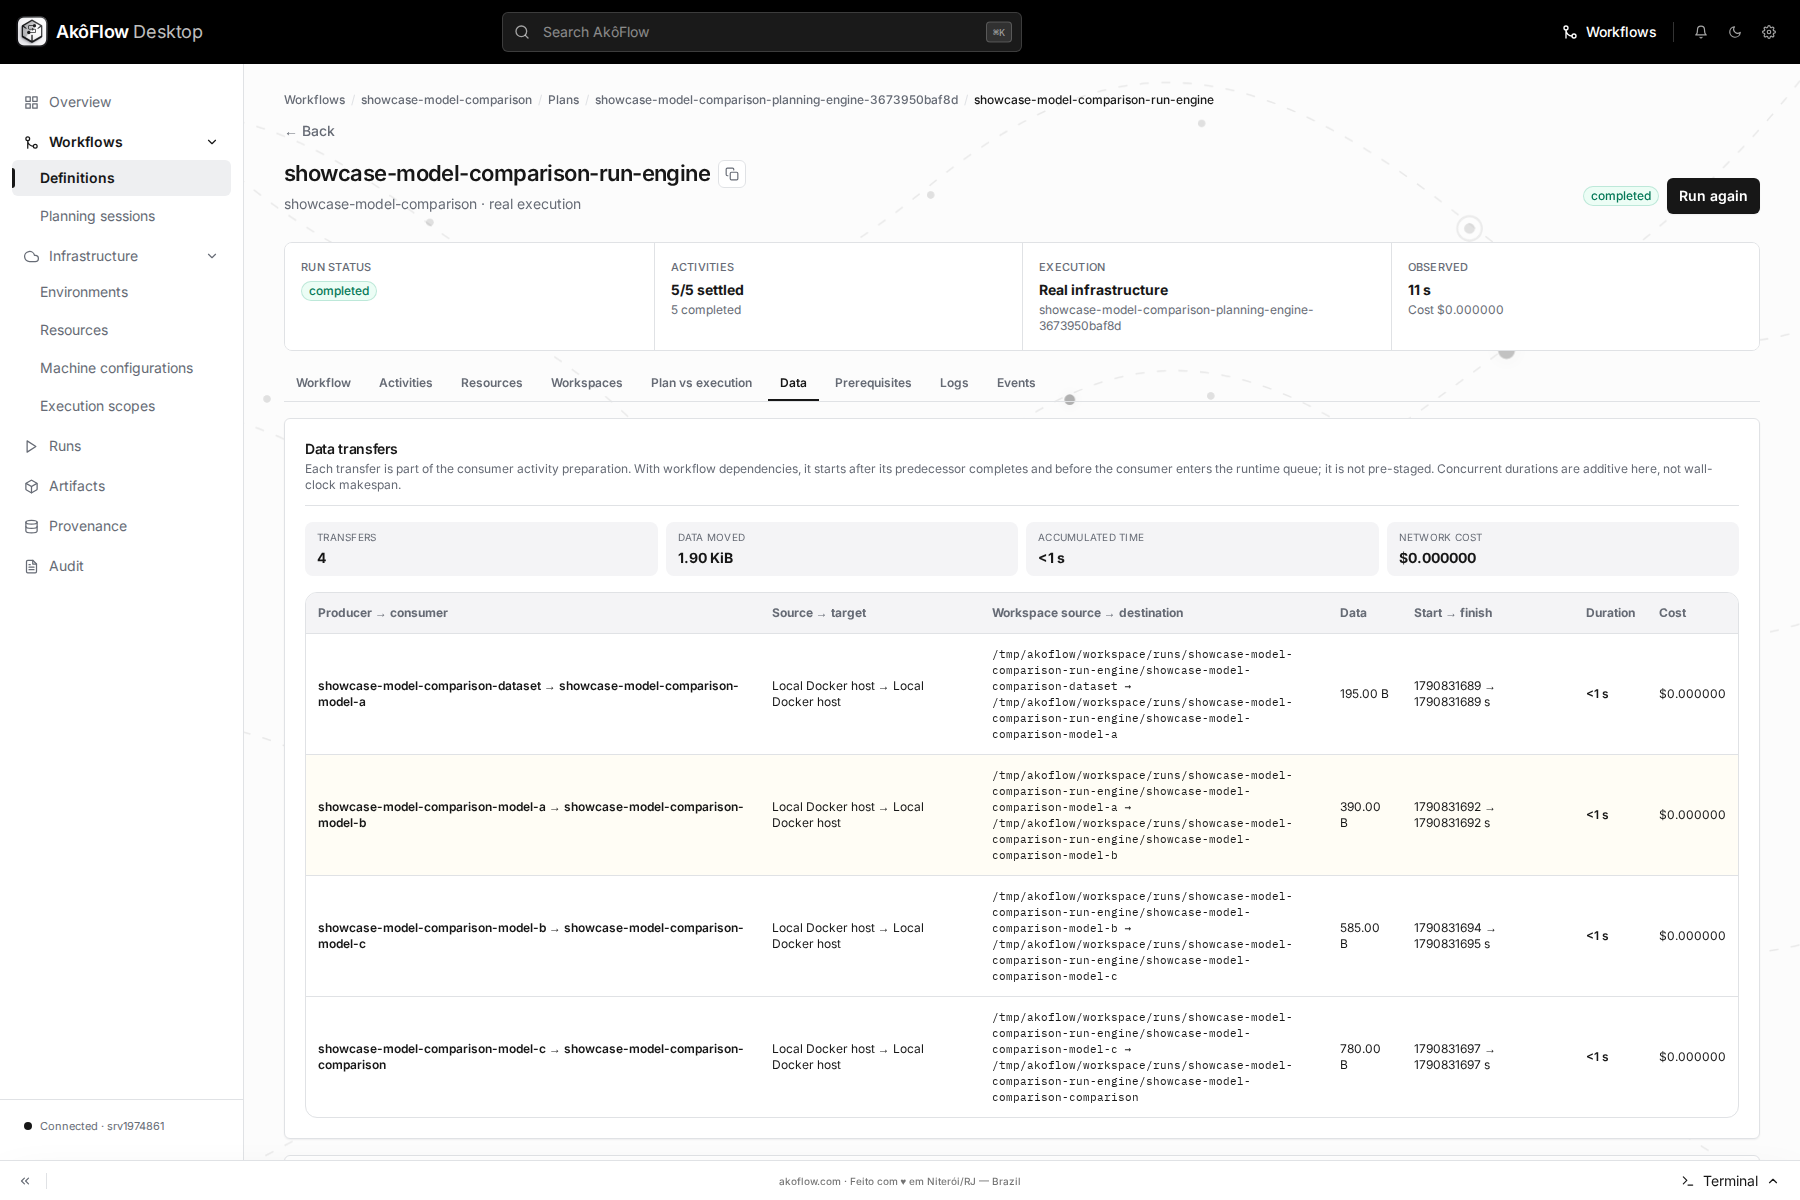
Execution considerations
Use comparable resources when latency is part of the decision. Keep quality and execution performance as separate measurements.
AkôFlow boundary: the engine schedules, deploys, executes, transfers data, and records evidence. The ML or agent framework remains an implementation choice inside each activity.